The measurements behind the claims.
Benchmarks, model reports and the code behind our evaluations.
Omi Medical-1 Flash
Medical transcription at $0.18 per audio-hour, 38% below flagship batch pricing. English batch, processed in the US.
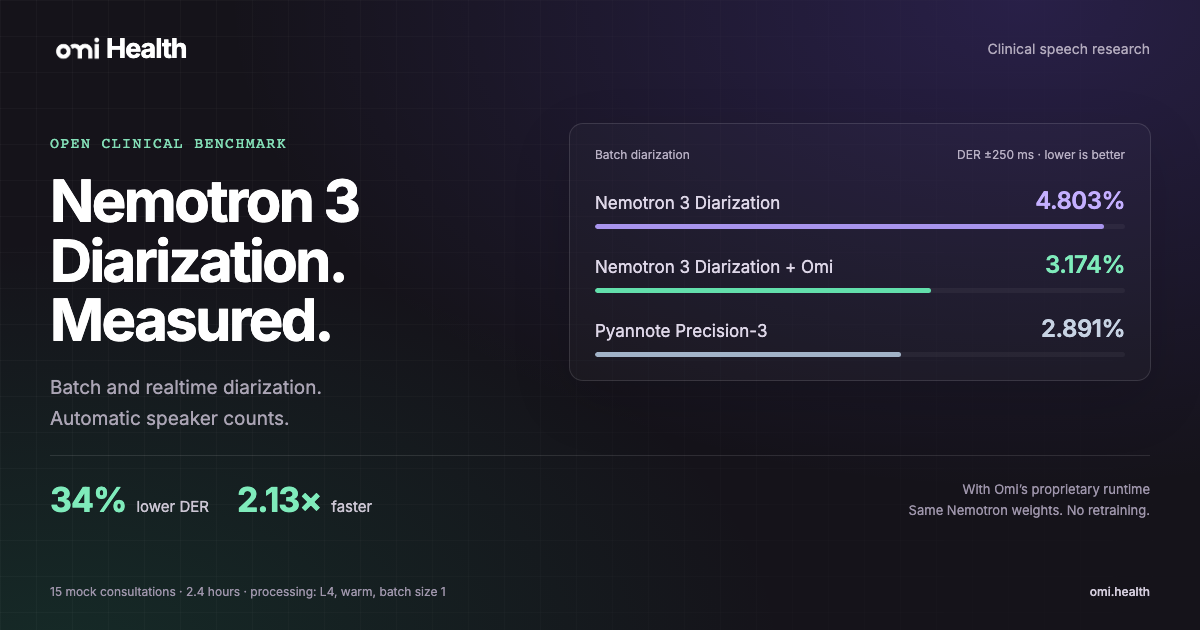
Nemotron 3 Diarization: who spoke, and when?
Batch and streaming diarization on clinical conversations, with open evaluation code and a separate Omi runtime comparison.
Same weights. 21–23% lower WER.
How a better NeMo result led us through the CUDA, Apple MLX and CPU inference paths.
Omi Medical v1.1
21% fewer realtime medical-term errors than v1, and new safeguards for silence and electrical hum.
AI Scribe Safety + Omi Guard
Eight frontier models tested with and without a deterministic safety layer. Guard recovered every measured miss and flagged all 12 confirmed hallucinations in this benchmark.
omi-medical-edge-1
An on-device 0.6B medical speech-to-text model for Apple Silicon, NVIDIA CUDA and CPU.
Clinical SOAP Note Evaluation
A safety-first SOAP benchmark measuring hallucinations, evidence grounding, and clinical coverage.
Omi-Sum 3B
An open 3B clinical model for structured SOAP notes, released under the MIT licence.
Repositories & models
omi-medical-edge-1 weights for local medical speech-to-text. CC-BY-4.0.
HuggingFace → omi-med-stt-runtimeRuntime CLI for omi-medical-edge-1 with MLX, NeMo and parakeet.cpp backends. MIT licence.
GitHub → medical-STT-evalEvaluation framework for speech-to-text models on medical conversations.
GitHub → medical-note-evalSOAP note safety benchmark for hallucination, grounding, and quality.
GitHub → sum-smallOmi-Sum 3B model weights and training dataset. MIT licence.
HuggingFace →